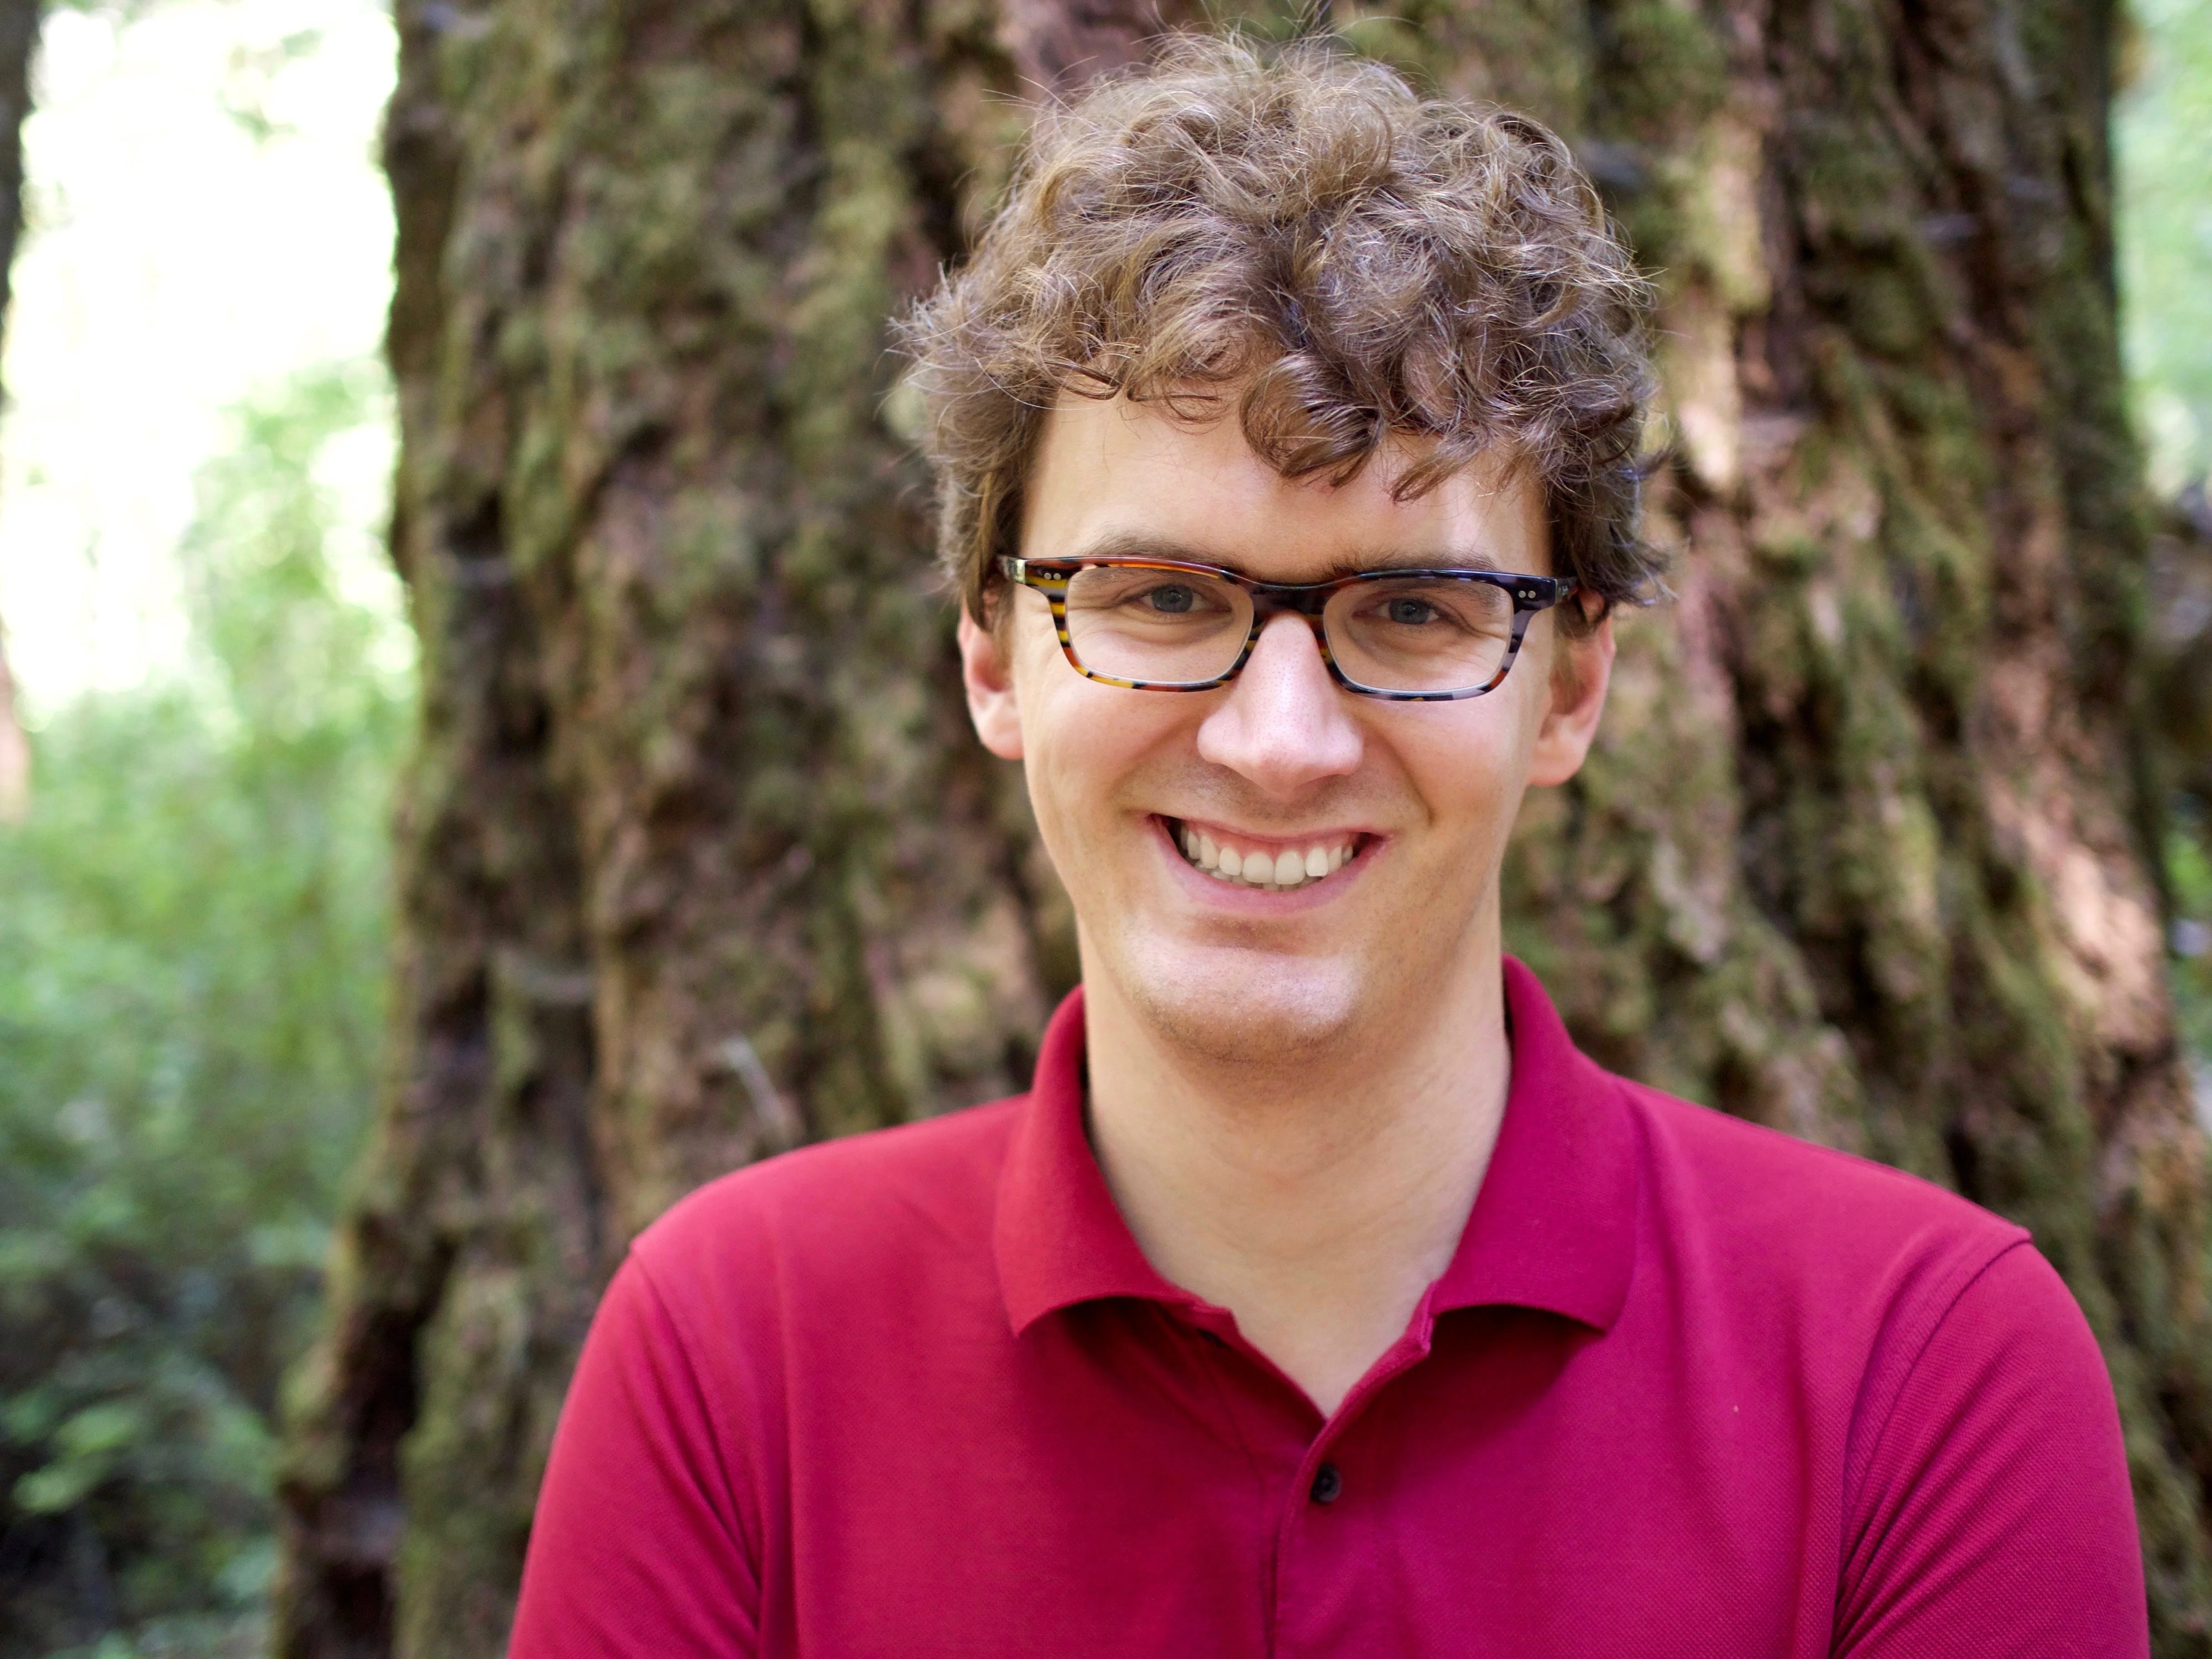
Brief Bio
I am a professor of computer science at Columbia, where I am a member of the Columbia Core AI Lab (CAIL). I am also a researcher at Apple.
I was previously a research scientist at Google and a visiting researcher at Cruise. I completed my PhD at MIT in 2017 advised by Antonio Torralba and my BS at UC Irvine in 2011, where I got my start working with Deva Ramanan.
I received the 2024 PAMI Young Researcher Award and the 2021 NSF CAREER Award. I served as Senior Program Chair for ICLR in 2025 and General Chair in 2026, and currently sit on the board.
Research
By training machines to observe and interact with their surroundings, our research aims to create robust and versatile models for perception. Our lab often investigates visual models that capitalize on large amounts of unlabeled data and transfer across tasks and modalities. Other interests include robotics, interpretable models, and other modalities such as sound, language, and beyond.
The lab recruits one or two PhD students each year. Prospective PhD students should apply to the PhD program. Due to the volume of email we receive, we unfortunately cannot respond to emails about applications.
PhD Students and Postdocs
 Arjun Mani
 Junbang Liang
 Lennart Schulze
 Sreehari Rammohan
 Sruthi Sudhakar
Graduated PhD Students and Former Postdocs
- 2026Sachit Menon, Member of Technical Staff at Anthropic
- 2025Mia Chiquier, Research Scientist at Mistral
- 2025Utkarsh Mall, Assistant Professor at MBZUAI
- 2025Ruoshi Liu, Assistant Professor at UMD
- 2024Basile Van Hoorick, Research Scientist at TRI
- 2024Dídac Surís, Research Scientist at Meta
- 2023Chengzhi Mao, Assistant Professor at Rutgers
Recent Papers
LookThere! Sparse Vision by Reinforced SelectionSreehari Rammohan, Yousef Yassin, Anthony Fuller, Junfeng Wen, Carl Vondrick, Evan Shelhamer. NeurIPS 2026
BibTeX
@inproceedings{rammohan2026lookthere,
  title={LookThere! Sparse Vision by Reinforced Selection},
  author={Sreehari Rammohan and Yousef Yassin and Anthony Fuller and Junfeng Wen and Carl Vondrick and Evan Shelhamer},
  booktitle={NeurIPS 2026},
  year={2026},
  url={https://arxiv.org/abs/2609.04698}
}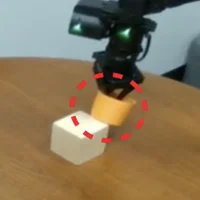
Robot Critics that Sweat the Small StuffSruthi Sudhakar, Junbang Liang, Sreehari Rammohan, Pavel Tokmakov, Richard Zemel, Carl Vondrick. arXiv 2026
@article{sudhakar2026robot,
  title={Robot Critics that Sweat the Small Stuff},
  author={Sruthi Sudhakar and Junbang Liang and Sreehari Rammohan and Pavel Tokmakov and Richard Zemel and Carl Vondrick},
  journal={arXiv 2026},
  year={2026},
  url={https://robocritic.cs.columbia.edu}
}
A²: Smaller Self-Supervised ViTs Localize Better than Larger OnesSreehari Rammohan, Huy Ha, Carl Vondrick. NeurIPS 2026
BibTeX
@inproceedings{rammohan2026a,
  title={A²: Smaller Self-Supervised ViTs Localize Better than Larger Ones},
  author={Sreehari Rammohan and Huy Ha and Carl Vondrick},
  booktitle={NeurIPS 2026},
  year={2026},
  url={https://arxiv.org/abs/2606.03148}
}
Do multimodal models imagine electric sheep?Santhosh Kumar Ramakrishnan, Carl Vondrick, Raja Giryes, Philipp Krähenbühl, Vladlen Koltun. NeurIPS 2026
BibTeX
@inproceedings{ramakrishnan2026do,
  title={Do multimodal models imagine electric sheep?},
  author={Santhosh Kumar Ramakrishnan and Carl Vondrick and Raja Giryes and Philipp Krähenbühl and Vladlen Koltun},
  booktitle={NeurIPS 2026},
  year={2026},
  url={https://arxiv.org/abs/2605.09693}
}
Few-Shot Design Optimization by Exploiting Auxiliary InformationArjun Mani, Carl Vondrick, Richard Zemel. ICML 2026
@inproceedings{mani2026fewshot,
  title={Few-Shot Design Optimization by Exploiting Auxiliary Information},
  author={Arjun Mani and Carl Vondrick and Richard Zemel},
  booktitle={ICML 2026},
  year={2026},
  url={https://designopt.cs.columbia.edu}
}
New York Smells: A Large Multimodal Dataset for OlfactionEge Ozguroglu, Junbang Liang, Ruoshi Liu, Mia Chiquier, Michael DeTienne, Wesley Wei Qian, Alexandra Horowitz, Andrew Owens, Carl Vondrick. arXiv 2025
@article{ozguroglu2025new,
  title={New York Smells: A Large Multimodal Dataset for Olfaction},
  author={Ege Ozguroglu and Junbang Liang and Ruoshi Liu and Mia Chiquier and Michael DeTienne and Wesley Wei Qian and Alexandra Horowitz and Andrew Owens and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://smell.cs.columbia.edu}
}
Robotics
Multimodal learning for robotic perception and action.
Video Generators are Robot PoliciesJunbang Liang, Pavel Tokmakov, Ruoshi Liu, Sruthi Sudhakar, Paarth Shah, Rares Ambrus, Carl Vondrick. arXiv 2025
@article{liang2025video,
  title={Video Generators are Robot Policies},
  author={Junbang Liang and Pavel Tokmakov and Ruoshi Liu and Sruthi Sudhakar and Paarth Shah and Rares Ambrus and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://arxiv.org/abs/2508.00795}
}
Self-Improving Autonomous Underwater ManipulationRuoshi Liu, Huy Ha, Mengxue Hou, Shuran Song, Carl Vondrick. ICRA 2025
@article{liu2025selfimproving,
  title={Self-Improving Autonomous Underwater Manipulation},
  author={Ruoshi Liu and Huy Ha and Mengxue Hou and Shuran Song and Carl Vondrick},
  journal={ICRA 2025},
  year={2025},
  url={https://aquabot.cs.columbia.edu}
}
Dreamitate: Real-World Visuomotor Policy Learning via Video GenerationJunbang Liang*, Ruoshi Liu*, Ege Ozguroglu, Sruthi Sudhakar, Achal Dave, Pavel Tokmakov, Shuran Song, Carl Vondrick. CoRL 2024
@inproceedings{liang2024dreamitate,
  title={Dreamitate: Real-World Visuomotor Policy Learning via Video Generation},
  author={Junbang Liang and Ruoshi Liu and Ege Ozguroglu and Sruthi Sudhakar and Achal Dave and Pavel Tokmakov and Shuran Song and Carl Vondrick},
  booktitle={CoRL 2024},
  year={2024},
  url={https://dreamitate.cs.columbia.edu}
}
PaperBot: Learning to Design Real-World Tools Using PaperRuoshi Liu, Junbang Liang, Sruthi Sudhakar, Huy Ha, Cheng Chi, Shuran Song, Carl Vondrick. arXiv 2024
@article{liu2024paperbot,
  title={PaperBot: Learning to Design Real-World Tools Using Paper},
  author={Ruoshi Liu and Junbang Liang and Sruthi Sudhakar and Huy Ha and Cheng Chi and Shuran Song and Carl Vondrick},
  journal={arXiv 2024},
  year={2024},
  url={https://paperbot.cs.columbia.edu}
}
Interpretability
Perception models that people can audit and reprogram.
SelfIE: Self-Interpretation of Large Language Model EmbeddingsHaozhe Chen, Carl Vondrick, Chengzhi Mao. ICML 2024
@inproceedings{chen2024selfie,
  title={SelfIE: Self-Interpretation of Large Language Model Embeddings},
  author={Haozhe Chen and Carl Vondrick and Chengzhi Mao},
  booktitle={ICML 2024},
  year={2024},
  url={https://selfie.cs.columbia.edu}
}
ViperGPT: Visual Inference via Python Execution for ReasoningDídac Surís*, Sachit Menon*, Carl Vondrick. ICCV 2023 (Oral)
@inproceedings{surís2023vipergpt,
  title={ViperGPT: Visual Inference via Python Execution for Reasoning},
  author={Dídac Surís and Sachit Menon and Carl Vondrick},
  booktitle={ICCV 2023 (Oral)},
  year={2023},
  url={https://viper.cs.columbia.edu}
}
Visual Classification via Description from Large Language ModelsSachit Menon, Carl Vondrick. ICLR 2023 (Oral)
@inproceedings{menon2023visual,
  title={Visual Classification via Description from Large Language Models},
  author={Sachit Menon and Carl Vondrick},
  booktitle={ICLR 2023 (Oral)},
  year={2023},
  url={https://arxiv.org/abs/2210.07183}
}
HOGgles: Visualizing Object Detection FeaturesCarl Vondrick, Aditya Khosla, Tomasz Malisiewicz, Antonio Torralba. ICCV 2013 (Oral)
@inproceedings{vondrick2013hoggles,
  title={HOGgles: Visualizing Object Detection Features},
  author={Carl Vondrick and Aditya Khosla and Tomasz Malisiewicz and Antonio Torralba},
  booktitle={ICCV 2013 (Oral)},
  year={2013},
  url={https://www.cs.columbia.edu/~vondrick/ihog}
}
AI4Science
Visual methods to accelerate scientific discovery.
Teaching Humans Subtle Differences with DIFF-usionMia Chiquier*, Orr Avrech*, Yossi Gandelsman, Berthy Feng, Katherine Bouman, Carl Vondrick. arXiv 2025
@article{chiquier2025teaching,
  title={Teaching Humans Subtle Differences with DIFF-usion},
  author={Mia Chiquier and Orr Avrech and Yossi Gandelsman and Berthy Feng and Katherine Bouman and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://diff-usion.cs.columbia.edu}
}
DiSciPLE: Learning Interpretable Programs for Scientific Visual DiscoveryUtkarsh Mall, Cheng Perng Phoo, Mia Chiquier, Bharath Hariharan, Kavita Bala, Carl Vondrick. CVPR 2025
@inproceedings{mall2025disciple,
  title={DiSciPLE: Learning Interpretable Programs for Scientific Visual Discovery},
  author={Utkarsh Mall and Cheng Perng Phoo and Mia Chiquier and Bharath Hariharan and Kavita Bala and Carl Vondrick},
  booktitle={CVPR 2025},
  year={2025},
  url={https://disciple.cs.columbia.edu}
}
Video
Learning perceptual skills from unlabeled video without manual supervision.
Tracking through Containers and Occluders in the WildBasile Van Hoorick, Pavel Tokmakov, Simon Stent, Jie Li, Carl Vondrick. CVPR 2023
@inproceedings{hoorick2023tracking,
  title={Tracking through Containers and Occluders in the Wild},
  author={Basile Van Hoorick and Pavel Tokmakov and Simon Stent and Jie Li and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://tcow.cs.columbia.edu}
}
Representing Spatial Trajectories as DistributionsDídac Surís, Carl Vondrick. NeurIPS 2022
@inproceedings{surís2022representing,
  title={Representing Spatial Trajectories as Distributions},
  author={Dídac Surís and Carl Vondrick},
  booktitle={NeurIPS 2022},
  year={2022},
  url={https://trajectories.cs.columbia.edu}
}
VideoBERT: A Joint Model for Video and Language Representation LearningChen Sun, Austin Myers, Carl Vondrick, Kevin Murphy, Cordelia Schmid. ICCV 2019
@inproceedings{sun2019videobert,
  title={VideoBERT: A Joint Model for Video and Language Representation Learning},
  author={Chen Sun and Austin Myers and Carl Vondrick and Kevin Murphy and Cordelia Schmid},
  booktitle={ICCV 2019},
  year={2019},
  url={https://arxiv.org/abs/1904.01766}
}
Tracking Emerges by Colorizing VideosCarl Vondrick, Abhinav Shrivastava, Alireza Fathi, Sergio Guadarrama, Kevin Murphy. ECCV 2018
@inproceedings{vondrick2018tracking,
  title={Tracking Emerges by Colorizing Videos},
  author={Carl Vondrick and Abhinav Shrivastava and Alireza Fathi and Sergio Guadarrama and Kevin Murphy},
  booktitle={ECCV 2018},
  year={2018},
  url={https://arxiv.org/pdf/1806.09594.pdf}
}
Assessing the Quality of ActionsHamed Pirsiavash, Carl Vondrick, Antonio Torralba. ECCV 2014
@inproceedings{pirsiavash2014assessing,
  title={Assessing the Quality of Actions},
  author={Hamed Pirsiavash and Carl Vondrick and Antonio Torralba},
  booktitle={ECCV 2014},
  year={2014},
  url={https://www.cs.columbia.edu/~vondrick/quality.pdf}
}
Prediction
Models that forecast future events and actions before they happen.
Learning the Predictability of the FutureDídac Surís*, Ruoshi Liu*, Carl Vondrick. CVPR 2021
@inproceedings{surís2021learning,
  title={Learning the Predictability of the Future},
  author={Dídac Surís and Ruoshi Liu and Carl Vondrick},
  booktitle={CVPR 2021},
  year={2021},
  url={https://arxiv.org/pdf/2101.01600.pdf}
}
Oops! Predicting Unintentional Action in VideoDave Epstein, Boyuan Chen, Carl Vondrick. CVPR 2020
@inproceedings{epstein2020oops,
  title={Oops! Predicting Unintentional Action in Video},
  author={Dave Epstein and Boyuan Chen and Carl Vondrick},
  booktitle={CVPR 2020},
  year={2020},
  url={https://arxiv.org/pdf/1911.11206.pdf}
}
Generating Videos with Scene DynamicsCarl Vondrick, Hamed Pirsiavash, Antonio Torralba. NeurIPS 2016
@inproceedings{vondrick2016generating,
  title={Generating Videos with Scene Dynamics},
  author={Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  booktitle={NeurIPS 2016},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/tinyvideo/}
}
Anticipating Visual Representations from Unlabeled VideoCarl Vondrick, Hamed Pirsiavash, Antonio Torralba. CVPR 2016 (Spotlight)
@inproceedings{vondrick2016anticipating,
  title={Anticipating Visual Representations from Unlabeled Video},
  author={Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  booktitle={CVPR 2016 (Spotlight)},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/prediction}
}
Multimodal
Cross-modal representations linking vision, sound, and language.
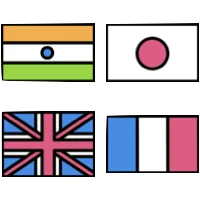
Globetrotter: Connecting Languages by Connecting ImagesDídac Surís, Dave Epstein, Carl Vondrick. CVPR 2022 (Oral)
@inproceedings{surís2022globetrotter,
  title={Globetrotter: Connecting Languages by Connecting Images},
  author={Dídac Surís and Dave Epstein and Carl Vondrick},
  booktitle={CVPR 2022 (Oral)},
  year={2022},
  url={https://arxiv.org/pdf/2012.04631.pdf}
}
Real-Time Neural Voice CamouflageMia Chiquier, Chengzhi Mao, Carl Vondrick. ICLR 2022 (Oral)
@inproceedings{chiquier2022realtime,
  title={Real-Time Neural Voice Camouflage},
  author={Mia Chiquier and Chengzhi Mao and Carl Vondrick},
  booktitle={ICLR 2022 (Oral)},
  year={2022},
  url={https://voicecamo.cs.columbia.edu}
}
The Boombox: Visual Reconstruction from Acoustic VibrationsBoyuan Chen, Mia Chiquier, Hod Lipson, Carl Vondrick. CoRL 2021
@inproceedings{chen2021the,
  title={The Boombox: Visual Reconstruction from Acoustic Vibrations},
  author={Boyuan Chen and Mia Chiquier and Hod Lipson and Carl Vondrick},
  booktitle={CoRL 2021},
  year={2021},
  url={https://arxiv.org/abs/2105.08052}
}
The Sound of PixelsHang Zhao, Chuang Gan, Andrew Rouditchenko, Carl Vondrick, Josh McDermott, Antonio Torralba. ECCV 2018
@inproceedings{zhao2018the,
  title={The Sound of Pixels},
  author={Hang Zhao and Chuang Gan and Andrew Rouditchenko and Carl Vondrick and Josh McDermott and Antonio Torralba},
  booktitle={ECCV 2018},
  year={2018},
  url={https://arxiv.org/abs/1804.03160}
}
SoundNet: Learning Sound Representations from Unlabeled VideoYusuf Aytar*, Carl Vondrick*, Antonio Torralba. NeurIPS 2016
@inproceedings{aytar2016soundnet,
  title={SoundNet: Learning Sound Representations from Unlabeled Video},
  author={Yusuf Aytar and Carl Vondrick and Antonio Torralba},
  booktitle={NeurIPS 2016},
  year={2016},
  url={https://projects.csail.mit.edu/soundnet/}
}
3D
Spatial awareness for 3D reconstruction and physical reasoning.
Generative Camera Dolly: Extreme Monocular Dynamic Novel View SynthesisBasile Van Hoorick, Rundi Wu, Ege Ozguroglu, Kyle Sargent, Ruoshi Liu, Pavel Tokmakov, Achal Dave, Changxi Zheng, Carl Vondrick. ECCV 2024 (Oral)
@inproceedings{hoorick2024generative,
  title={Generative Camera Dolly: Extreme Monocular Dynamic Novel View Synthesis},
  author={Basile Van Hoorick and Rundi Wu and Ege Ozguroglu and Kyle Sargent and Ruoshi Liu and Pavel Tokmakov and Achal Dave and Changxi Zheng and Carl Vondrick},
  booktitle={ECCV 2024 (Oral)},
  year={2024},
  url={https://gcd.cs.columbia.edu}
}
pix2gestalt: Amodal Segmentation by Synthesizing WholesEge Ozguroglu, Ruoshi Liu, Dídac Surís, Dian Chen, Achal Dave, Pavel Tokmakov, Carl Vondrick. CVPR 2024
@inproceedings{ozguroglu2024pixgestalt,
  title={pix2gestalt: Amodal Segmentation by Synthesizing Wholes},
  author={Ege Ozguroglu and Ruoshi Liu and Dídac Surís and Dian Chen and Achal Dave and Pavel Tokmakov and Carl Vondrick},
  booktitle={CVPR 2024},
  year={2024},
  url={https://gestalt.cs.columbia.edu}
}
Objaverse-XL: A Universe of 10M+ 3D ObjectsMatt Deitke et al. NeurIPS 2023
BibTeX
@inproceedings{deitke2023objaversexl,
  title={Objaverse-XL: A Universe of 10M+ 3D Objects},
  author={Matt Deitke and others},
  booktitle={NeurIPS 2023},
  year={2023},
  url={https://objaverse.allenai.org/objaverse-xl-paper.pdf}
}
Zero-1-to-3: Zero-shot One Image to 3D ObjectRuoshi Liu, Rundi Wu, Basile Van Hoorick, Pavel Tokmakov, Sergey Zakharov, Carl Vondrick. ICCV 2023 (Oral)
@inproceedings{liu2023zeroto,
  title={Zero-1-to-3: Zero-shot One Image to 3D Object},
  author={Ruoshi Liu and Rundi Wu and Basile Van Hoorick and Pavel Tokmakov and Sergey Zakharov and Carl Vondrick},
  booktitle={ICCV 2023 (Oral)},
  year={2023},
  url={https://zero123.cs.columbia.edu}
}
SurfsUp: Learning Fluid Simulation for Novel SurfacesArjun Mani*, Ishaan Preetam Chandratreya*, Elliot Creager, Carl Vondrick, Richard Zemel. ICCV 2023
@inproceedings{mani2023surfsup,
  title={SurfsUp: Learning Fluid Simulation for Novel Surfaces},
  author={Arjun Mani and Ishaan Preetam Chandratreya and Elliot Creager and Carl Vondrick and Richard Zemel},
  booktitle={ICCV 2023},
  year={2023},
  url={https://surfsup.cs.columbia.edu}
}
Humans as Light Bulbs: 3D Human Reconstruction from Thermal ReflectionRuoshi Liu, Carl Vondrick. CVPR 2023
@inproceedings{liu2023humans,
  title={Humans as Light Bulbs: 3D Human Reconstruction from Thermal Reflection},
  author={Ruoshi Liu and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://thermal.cs.columbia.edu}
}
Robustness
Trustworthy models with strong generalization under distribution shift.
Raidar: geneRative AI Detection viA RewritingChengzhi Mao, Carl Vondrick, Hao Wang, Junfeng Yang. ICLR 2024
BibTeX
@inproceedings{mao2024raidar,
  title={Raidar: geneRative AI Detection viA Rewriting},
  author={Chengzhi Mao and Carl Vondrick and Hao Wang and Junfeng Yang},
  booktitle={ICLR 2024},
  year={2024},
  url={https://arxiv.org/pdf/2401.12970.pdf}
}
Adversarial Attacks are Reversible with Natural SupervisionChengzhi Mao, Mia Chiquier, Hao Wang, Junfeng Yang, Carl Vondrick. ICCV 2021
@inproceedings{mao2021adversarial,
  title={Adversarial Attacks are Reversible with Natural Supervision},
  author={Chengzhi Mao and Mia Chiquier and Hao Wang and Junfeng Yang and Carl Vondrick},
  booktitle={ICCV 2021},
  year={2021},
  url={https://arxiv.org/abs/2103.14222}
}
Metric Learning for Adversarial RobustnessChengzhi Mao, Ziyuan Zhong, Junfeng Yang, Carl Vondrick, Baishakhi Ray. NeurIPS 2019
@inproceedings{mao2019metric,
  title={Metric Learning for Adversarial Robustness},
  author={Chengzhi Mao and Ziyuan Zhong and Junfeng Yang and Carl Vondrick and Baishakhi Ray},
  booktitle={NeurIPS 2019},
  year={2019},
  url={https://arxiv.org/abs/1909.00900}
}
For all papers, see the complete list.
Teaching
- Computer Vision II, Summer 2021, Spring 2022–2025
- Computer Vision I, Fall 2018–2019
- Advanced Computer Vision, Spring 2019
- Machine Learning Frontiers, Fall 2024–2025
- Representation Learning, Fall 2020–2022
Funding
- National Science Foundation
- Defense Advanced Research Projects Agency
- Toyota Research Institute
- Amazon Research