All Papers
2026
LookThere! Sparse Vision by Reinforced Selection
Sreehari Rammohan, Yousef Yassin, Anthony Fuller, Junfeng Wen, Carl Vondrick, Evan Shelhamer
arXiv 2026
BibTeX
@article{rammohan2026lookthere,
  title={LookThere! Sparse Vision by Reinforced Selection},
  author={Sreehari Rammohan and Yousef Yassin and Anthony Fuller and Junfeng Wen and Carl Vondrick and Evan Shelhamer},
  journal={arXiv 2026},
  year={2026},
  url={https://arxiv.org/abs/2609.04698}
}
Robot Critics that Sweat the Small Stuff
Sruthi Sudhakar, Junbang Liang, Sreehari Rammohan, Pavel Tokmakov, Richard Zemel, Carl Vondrick
arXiv 2026
@article{sudhakar2026robot,
  title={Robot Critics that Sweat the Small Stuff},
  author={Sruthi Sudhakar and Junbang Liang and Sreehari Rammohan and Pavel Tokmakov and Richard Zemel and Carl Vondrick},
  journal={arXiv 2026},
  year={2026},
  url={https://robocritic.cs.columbia.edu}
}
A²: Smaller Self-Supervised ViTs Localize Better than Larger Ones
Sreehari Rammohan, Huy Ha, Carl Vondrick
arXiv 2026
BibTeX
@article{rammohan2026a,
  title={A²: Smaller Self-Supervised ViTs Localize Better than Larger Ones},
  author={Sreehari Rammohan and Huy Ha and Carl Vondrick},
  journal={arXiv 2026},
  year={2026},
  url={https://arxiv.org/abs/2606.03148}
}
Do multimodal models imagine electric sheep?
Santhosh Kumar Ramakrishnan, Carl Vondrick, Raja Giryes, Philipp Krähenbühl, Vladlen Koltun
arXiv 2026
BibTeX
@article{ramakrishnan2026do,
  title={Do multimodal models imagine electric sheep?},
  author={Santhosh Kumar Ramakrishnan and Carl Vondrick and Raja Giryes and Philipp Krähenbühl and Vladlen Koltun},
  journal={arXiv 2026},
  year={2026},
  url={https://arxiv.org/abs/2605.09693}
}
Few-Shot Design Optimization by Exploiting Auxiliary Information
Arjun Mani, Carl Vondrick, Richard Zemel
ICML 2026
@inproceedings{mani2026fewshot,
  title={Few-Shot Design Optimization by Exploiting Auxiliary Information},
  author={Arjun Mani and Carl Vondrick and Richard Zemel},
  booktitle={ICML 2026},
  year={2026},
  url={https://designopt.cs.columbia.edu}
}
2025
New York Smells: A Large Multimodal Dataset for Olfaction
Ege Ozguroglu, Junbang Liang, Ruoshi Liu, Mia Chiquier, Michael DeTienne, Wesley Wei Qian, Alexandra Horowitz, Andrew Owens, Carl Vondrick
arXiv 2025
@article{ozguroglu2025new,
  title={New York Smells: A Large Multimodal Dataset for Olfaction},
  author={Ege Ozguroglu and Junbang Liang and Ruoshi Liu and Mia Chiquier and Michael DeTienne and Wesley Wei Qian and Alexandra Horowitz and Andrew Owens and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://smell.cs.columbia.edu}
}
Video Generators are Robot Policies
Junbang Liang, Pavel Tokmakov, Ruoshi Liu, Sruthi Sudhakar, Paarth Shah, Rares Ambrus, Carl Vondrick
arXiv 2025
@article{liang2025video,
  title={Video Generators are Robot Policies},
  author={Junbang Liang and Pavel Tokmakov and Ruoshi Liu and Sruthi Sudhakar and Paarth Shah and Rares Ambrus and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://arxiv.org/abs/2508.00795}
}
MINERVA: Evaluating Complex Video Reasoning
Arsha Nagrani, Sachit Menon, Ahmet Iscen, Shyamal Buch, Ramin Mehran, Nilpa Jha, Anja Hauth, Yukun Zhu, Carl Vondrick, Mikhail Sirotenko, Cordelia Schmid, Tobias Weyand
ICCV 2025
@inproceedings{nagrani2025minerva,
  title={MINERVA: Evaluating Complex Video Reasoning},
  author={Arsha Nagrani and Sachit Menon and Ahmet Iscen and Shyamal Buch and Ramin Mehran and Nilpa Jha and Anja Hauth and Yukun Zhu and Carl Vondrick and Mikhail Sirotenko and Cordelia Schmid and Tobias Weyand},
  booktitle={ICCV 2025},
  year={2025},
  url={https://arxiv.org/abs/2505.00681}
}
Towards LLM Agents for Earth Observation
Chia Hsiang Kao, Wenting Zhao, Shreelekha Revankar, Samuel Speas, Snehal Bhagat, Rajeev Datta, Cheng Perng Phoo, Utkarsh Mall, Carl Vondrick, Kavita Bala, Bharath Hariharan
arXiv 2025
@article{kao2025towards,
  title={Towards LLM Agents for Earth Observation},
  author={Chia Hsiang Kao and Wenting Zhao and Shreelekha Revankar and Samuel Speas and Snehal Bhagat and Rajeev Datta and Cheng Perng Phoo and Utkarsh Mall and Carl Vondrick and Kavita Bala and Bharath Hariharan},
  journal={arXiv 2025},
  year={2025},
  url={https://arxiv.org/abs/2504.12110}
}
Teaching Humans Subtle Differences with DIFF-usion
Mia Chiquier*, Orr Avrech*, Yossi Gandelsman, Berthy Feng, Katherine Bouman, Carl Vondrick
arXiv 2025
@article{chiquier2025teaching,
  title={Teaching Humans Subtle Differences with DIFF-usion},
  author={Mia Chiquier and Orr Avrech and Yossi Gandelsman and Berthy Feng and Katherine Bouman and Carl Vondrick},
  journal={arXiv 2025},
  year={2025},
  url={https://diff-usion.cs.columbia.edu}
}
Generative Data Mining with Longtail-Guided Diffusion
David S. Hayden, Mao Ye, Timur Garipov, Gregory P. Meyer, Carl Vondrick, Zhao Chen, Yuning Chai, Eric Wolff, Siddhartha S. Srinivasa
ICML 2025
BibTeX
@inproceedings{hayden2025generative,
  title={Generative Data Mining with Longtail-Guided Diffusion},
  author={David S. Hayden and Mao Ye and Timur Garipov and Gregory P. Meyer and Carl Vondrick and Zhao Chen and Yuning Chai and Eric Wolff and Siddhartha S. Srinivasa},
  booktitle={ICML 2025},
  year={2025},
  url={https://arxiv.org/abs/2502.01980}
}
DiSciPLE: Learning Interpretable Programs for Scientific Visual Discovery
Utkarsh Mall, Cheng Perng Phoo, Mia Chiquier, Bharath Hariharan, Kavita Bala, Carl Vondrick
CVPR 2025
@inproceedings{mall2025disciple,
  title={DiSciPLE: Learning Interpretable Programs for Scientific Visual Discovery},
  author={Utkarsh Mall and Cheng Perng Phoo and Mia Chiquier and Bharath Hariharan and Kavita Bala and Carl Vondrick},
  booktitle={CVPR 2025},
  year={2025},
  url={https://disciple.cs.columbia.edu}
}
Self-Improving Autonomous Underwater Manipulation
Ruoshi Liu, Huy Ha, Mengxue Hou, Shuran Song, Carl Vondrick
ICRA 2025
@article{liu2025selfimproving,
  title={Self-Improving Autonomous Underwater Manipulation},
  author={Ruoshi Liu and Huy Ha and Mengxue Hou and Shuran Song and Carl Vondrick},
  journal={ICRA 2025},
  year={2025},
  url={https://aquabot.cs.columbia.edu}
}
2024
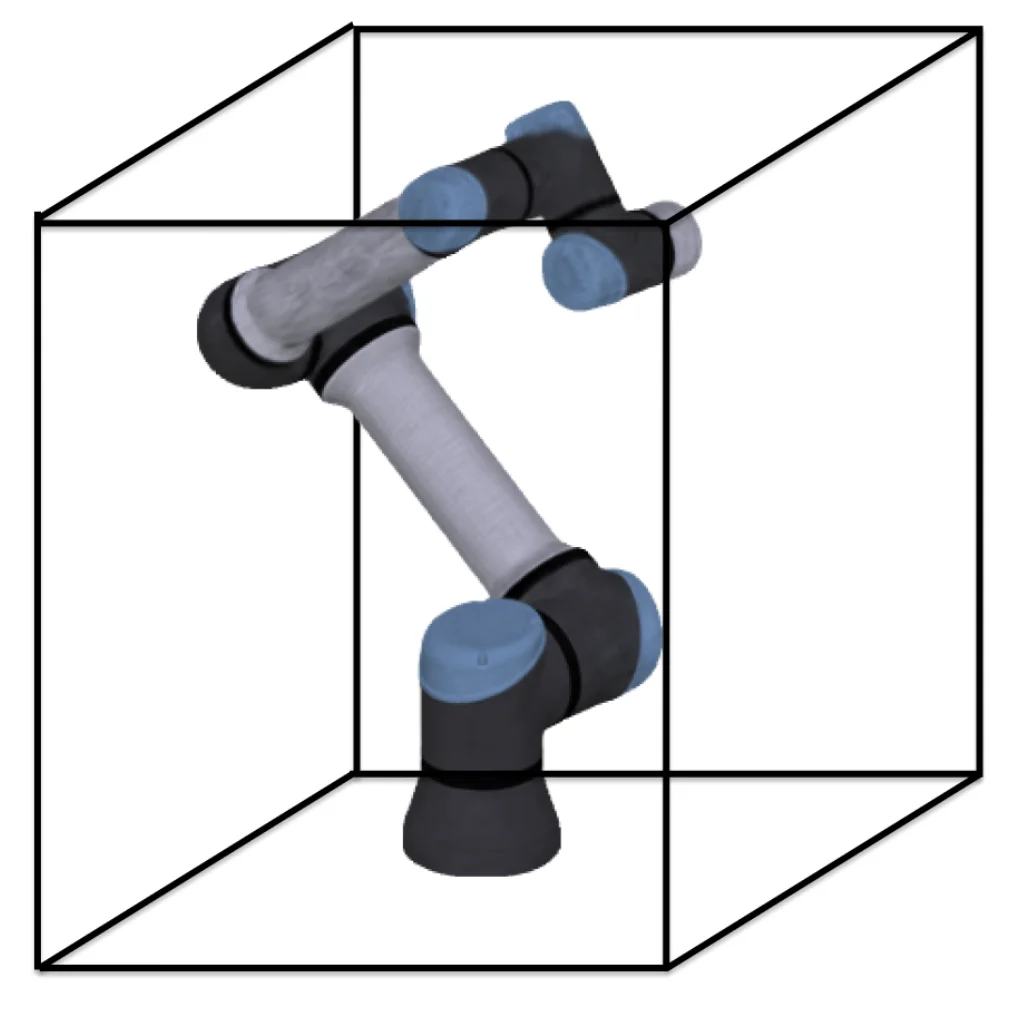
Differentiable Robot Rendering
Ruoshi Liu, Alper Canberk, Shuran Song, Carl Vondrick
CoRL 2024 (Oral)
@inproceedings{liu2024differentiable,
  title={Differentiable Robot Rendering},
  author={Ruoshi Liu and Alper Canberk and Shuran Song and Carl Vondrick},
  booktitle={CoRL 2024 (Oral)},
  year={2024},
  url={https://drrobot.cs.columbia.edu}
}
Dreamitate: Real-World Visuomotor Policy Learning via Video Generation
Junbang Liang*, Ruoshi Liu*, Ege Ozguroglu, Sruthi Sudhakar, Achal Dave, Pavel Tokmakov, Shuran Song, Carl Vondrick
CoRL 2024
@inproceedings{liang2024dreamitate,
  title={Dreamitate: Real-World Visuomotor Policy Learning via Video Generation},
  author={Junbang Liang and Ruoshi Liu and Ege Ozguroglu and Sruthi Sudhakar and Achal Dave and Pavel Tokmakov and Shuran Song and Carl Vondrick},
  booktitle={CoRL 2024},
  year={2024},
  url={https://dreamitate.cs.columbia.edu}
}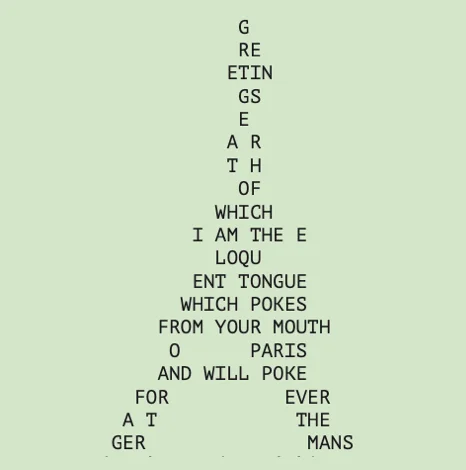
Whiteboard-of-Thought: Thinking Step-by-Step Across Modalities
Sachit Menon, Richard Zemel, Carl Vondrick
EMNLP 2024
@inproceedings{menon2024whiteboardofthought,
  title={Whiteboard-of-Thought: Thinking Step-by-Step Across Modalities},
  author={Sachit Menon and Richard Zemel and Carl Vondrick},
  booktitle={EMNLP 2024},
  year={2024},
  url={https://whiteboard.cs.columbia.edu}
}
EraseDraw: Learning to Draw Step-by-Step via Erasing Objects from Images
Alper Canberk, Maksym Bondarenko, Ege Ozguroglu, Ruoshi Liu, Carl Vondrick
ECCV 2024
@inproceedings{canberk2024erasedraw,
  title={EraseDraw: Learning to Draw Step-by-Step via Erasing Objects from Images},
  author={Alper Canberk and Maksym Bondarenko and Ege Ozguroglu and Ruoshi Liu and Carl Vondrick},
  booktitle={ECCV 2024},
  year={2024},
  url={https://erasedraw.cs.columbia.edu}
}
How Video Meetings Change Your Expression
Sumit Sarin, Utkarsh Mall, Purva Tendulkar, Carl Vondrick
ECCV 2024
@inproceedings{sarin2024how,
  title={How Video Meetings Change Your Expression},
  author={Sumit Sarin and Utkarsh Mall and Purva Tendulkar and Carl Vondrick},
  booktitle={ECCV 2024},
  year={2024},
  url={https://facet.cs.columbia.edu}
}
Controlling the World by Sleight of Hand
Sruthi Sudhakar, Ruoshi Liu, Basile Van Hoorick, Carl Vondrick, and Richard Zemel
ECCV 2024 (Oral)
BibTeX
@inproceedings{sudhakar2024controlling,
  title={Controlling the World by Sleight of Hand},
  author={Sruthi Sudhakar and Ruoshi Liu and Basile Van Hoorick and Carl Vondrick and and Richard Zemel},
  booktitle={ECCV 2024 (Oral)},
  year={2024},
  url={https://arxiv.org/pdf/2408.07147}
}
Generative Camera Dolly: Extreme Monocular Dynamic Novel View Synthesis
Basile Van Hoorick, Rundi Wu, Ege Ozguroglu, Kyle Sargent, Ruoshi Liu, Pavel Tokmakov, Achal Dave, Changxi Zheng, Carl Vondrick
ECCV 2024 (Oral)
@inproceedings{hoorick2024generative,
  title={Generative Camera Dolly: Extreme Monocular Dynamic Novel View Synthesis},
  author={Basile Van Hoorick and Rundi Wu and Ege Ozguroglu and Kyle Sargent and Ruoshi Liu and Pavel Tokmakov and Achal Dave and Changxi Zheng and Carl Vondrick},
  booktitle={ECCV 2024 (Oral)},
  year={2024},
  url={https://gcd.cs.columbia.edu}
}
Evolving Interpretable Visual Classifiers with Large Language Models
Mia Chiquier, Utkarsh Mall, Carl Vondrick
ECCV 2024
@inproceedings{chiquier2024evolving,
  title={Evolving Interpretable Visual Classifiers with Large Language Models},
  author={Mia Chiquier and Utkarsh Mall and Carl Vondrick},
  booktitle={ECCV 2024},
  year={2024},
  url={https://llm-mutate.cs.columbia.edu}
}
SelfIE: Self-Interpretation of Large Language Model Embeddings
Haozhe Chen, Carl Vondrick, Chengzhi Mao
ICML 2024
@inproceedings{chen2024selfie,
  title={SelfIE: Self-Interpretation of Large Language Model Embeddings},
  author={Haozhe Chen and Carl Vondrick and Chengzhi Mao},
  booktitle={ICML 2024},
  year={2024},
  url={https://selfie.cs.columbia.edu}
}
PaperBot: Learning to Design Real-World Tools Using Paper
Ruoshi Liu, Junbang Liang, Sruthi Sudhakar, Huy Ha, Cheng Chi, Shuran Song, Carl Vondrick
arXiv 2024
@article{liu2024paperbot,
  title={PaperBot: Learning to Design Real-World Tools Using Paper},
  author={Ruoshi Liu and Junbang Liang and Sruthi Sudhakar and Huy Ha and Cheng Chi and Shuran Song and Carl Vondrick},
  journal={arXiv 2024},
  year={2024},
  url={https://paperbot.cs.columbia.edu}
}
pix2gestalt: Amodal Segmentation by Synthesizing Wholes
Ege Ozguroglu, Ruoshi Liu, Dídac Surís, Dian Chen, Achal Dave, Pavel Tokmakov, Carl Vondrick
CVPR 2024
@inproceedings{ozguroglu2024pixgestalt,
  title={pix2gestalt: Amodal Segmentation by Synthesizing Wholes},
  author={Ege Ozguroglu and Ruoshi Liu and Dídac Surís and Dian Chen and Achal Dave and Pavel Tokmakov and Carl Vondrick},
  booktitle={CVPR 2024},
  year={2024},
  url={https://gestalt.cs.columbia.edu}
}
Raidar: geneRative AI Detection viA Rewriting
Chengzhi Mao, Carl Vondrick, Hao Wang, Junfeng Yang
ICLR 2024
BibTeX
@inproceedings{mao2024raidar,
  title={Raidar: geneRative AI Detection viA Rewriting},
  author={Chengzhi Mao and Carl Vondrick and Hao Wang and Junfeng Yang},
  booktitle={ICLR 2024},
  year={2024},
  url={https://arxiv.org/pdf/2401.12970.pdf}
}
Interpreting and Controlling Vision Foundation Models via Text Explanations
Haozhe Chen, Junfeng Yang, Carl Vondrick, Chengzhi Mao
ICLR 2024
BibTeX
@inproceedings{chen2024interpreting,
  title={Interpreting and Controlling Vision Foundation Models via Text Explanations},
  author={Haozhe Chen and Junfeng Yang and Carl Vondrick and Chengzhi Mao},
  booktitle={ICLR 2024},
  year={2024},
  url={https://arxiv.org/abs/2310.10591}
}
Sin3DM: Learning a Diffusion Model from a Single 3D Textured Shape
Rundi Wu, Ruoshi Liu, Carl Vondrick, Changxi Zheng
ICLR 2024
@inproceedings{wu2024sindm,
  title={Sin3DM: Learning a Diffusion Model from a Single 3D Textured Shape},
  author={Rundi Wu and Ruoshi Liu and Carl Vondrick and Changxi Zheng},
  booktitle={ICLR 2024},
  year={2024},
  url={https://sin3dm.github.io}
}
Remote Sensing Vision-Language Foundation Models without Annotations via Ground Remote Alignment
Utkarsh Mall, Cheng Perng Phoo, Meilin Liu, Carl Vondrick, Bharath Hariharan, Kavita Bala
ICLR 2024
BibTeX
@inproceedings{mall2024remote,
  title={Remote Sensing Vision-Language Foundation Models without Annotations via Ground Remote Alignment},
  author={Utkarsh Mall and Cheng Perng Phoo and Meilin Liu and Carl Vondrick and Bharath Hariharan and Kavita Bala},
  booktitle={ICLR 2024},
  year={2024},
  url={https://arxiv.org/pdf/2312.06960.pdf}
}
2023
Objaverse-XL: A Universe of 10M+ 3D Objects
Matt Deitke et al.
NeurIPS 2023
BibTeX
@inproceedings{deitke2023objaversexl,
  title={Objaverse-XL: A Universe of 10M+ 3D Objects},
  author={Matt Deitke and others},
  booktitle={NeurIPS 2023},
  year={2023},
  url={https://objaverse.allenai.org/objaverse-xl-paper.pdf}
}
ViperGPT: Visual Inference via Python Execution for Reasoning
Dídac Surís*, Sachit Menon*, Carl Vondrick
ICCV 2023 (Oral)
@inproceedings{surís2023vipergpt,
  title={ViperGPT: Visual Inference via Python Execution for Reasoning},
  author={Dídac Surís and Sachit Menon and Carl Vondrick},
  booktitle={ICCV 2023 (Oral)},
  year={2023},
  url={https://viper.cs.columbia.edu}
}
Zero-1-to-3: Zero-shot One Image to 3D Object
Ruoshi Liu, Rundi Wu, Basile Van Hoorick, Pavel Tokmakov, Sergey Zakharov, Carl Vondrick
ICCV 2023 (Oral)
@inproceedings{liu2023zeroto,
  title={Zero-1-to-3: Zero-shot One Image to 3D Object},
  author={Ruoshi Liu and Rundi Wu and Basile Van Hoorick and Pavel Tokmakov and Sergey Zakharov and Carl Vondrick},
  booktitle={ICCV 2023 (Oral)},
  year={2023},
  url={https://zero123.cs.columbia.edu}
}
Muscles in Action
Mia Chiquier, Carl Vondrick
ICCV 2023
@inproceedings{chiquier2023muscles,
  title={Muscles in Action},
  author={Mia Chiquier and Carl Vondrick},
  booktitle={ICCV 2023},
  year={2023},
  url={https://arxiv.org/abs/2212.02978}
}
SurfsUp: Learning Fluid Simulation for Novel Surfaces
Arjun Mani*, Ishaan Preetam Chandratreya*, Elliot Creager, Carl Vondrick, Richard Zemel
ICCV 2023
@inproceedings{mani2023surfsup,
  title={SurfsUp: Learning Fluid Simulation for Novel Surfaces},
  author={Arjun Mani and Ishaan Preetam Chandratreya and Elliot Creager and Carl Vondrick and Richard Zemel},
  booktitle={ICCV 2023},
  year={2023},
  url={https://surfsup.cs.columbia.edu}
}
Landscape Learning for Neural Network Inversion
Ruoshi Liu, Chengzhi Mao, Purva Tendulkar, Hao Wang, Carl Vondrick
ICCV 2023
@inproceedings{liu2023landscape,
  title={Landscape Learning for Neural Network Inversion},
  author={Ruoshi Liu and Chengzhi Mao and Purva Tendulkar and Hao Wang and Carl Vondrick},
  booktitle={ICCV 2023},
  year={2023},
  url={https://arxiv.org/abs/2206.09027}
}
SHIFT3D: Synthesizing Hard Inputs For Tricking 3D Detectors
Hongge Chen, Zhao Chen, Greg Meyer, Dennis Park, Carl Vondrick, Ashish Shrivastava, Yuning Chai
ICCV 2023
BibTeX
@inproceedings{chen2023shiftd,
  title={SHIFT3D: Synthesizing Hard Inputs For Tricking 3D Detectors},
  author={Hongge Chen and Zhao Chen and Greg Meyer and Dennis Park and Carl Vondrick and Ashish Shrivastava and Yuning Chai},
  booktitle={ICCV 2023},
  year={2023},
  url={https://openaccess.thecvf.com/content/ICCV2023/papers/Chen_SHIFT3D_Synthesizing_Hard_Inputs_For_Tricking_3D_Detectors_ICCV_2023_paper.pdf}
}
Robust Perception through Equivariance
Chengzhi Mao, Lingyu Zhang, Abhishek Joshi, Junfeng Yang, Hao Wang, Carl Vondrick
ICML 2023
@inproceedings{mao2023robust,
  title={Robust Perception through Equivariance},
  author={Chengzhi Mao and Lingyu Zhang and Abhishek Joshi and Junfeng Yang and Hao Wang and Carl Vondrick},
  booktitle={ICML 2023},
  year={2023},
  url={https://arxiv.org/abs/2212.06079}
}
Humans as Light Bulbs: 3D Human Reconstruction from Thermal Reflection
Ruoshi Liu, Carl Vondrick
CVPR 2023
@inproceedings{liu2023humans,
  title={Humans as Light Bulbs: 3D Human Reconstruction from Thermal Reflection},
  author={Ruoshi Liu and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://thermal.cs.columbia.edu}
}
What You Can Reconstruct from a Shadow
Ruoshi Liu, Sachit Menon, Chengzhi Mao, Dennis Park, Simon Stent, Carl Vondrick
CVPR 2023
@inproceedings{liu2023what,
  title={What You Can Reconstruct from a Shadow},
  author={Ruoshi Liu and Sachit Menon and Chengzhi Mao and Dennis Park and Simon Stent and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://openaccess.thecvf.com//content/CVPR2023/papers/Liu_What_You_Can_Reconstruct_From_a_Shadow_CVPR_2023_paper.pdf}
}
Tracking through Containers and Occluders in the Wild
Basile Van Hoorick, Pavel Tokmakov, Simon Stent, Jie Li, Carl Vondrick
CVPR 2023
@inproceedings{hoorick2023tracking,
  title={Tracking through Containers and Occluders in the Wild},
  author={Basile Van Hoorick and Pavel Tokmakov and Simon Stent and Jie Li and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://tcow.cs.columbia.edu}
}
FLEX: Full-Body Grasping Without Full-Body Grasps
Purva Tendulkar, Dídac Surís, Carl Vondrick
CVPR 2023
@inproceedings{tendulkar2023flex,
  title={FLEX: Full-Body Grasping Without Full-Body Grasps},
  author={Purva Tendulkar and Dídac Surís and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://flex.cs.columbia.edu/}
}
Doubly Right Object Recognition: A Why Prompt for Visual Rationales
Chengzhi Mao, Revant Teotia, Amrutha Sundar, Sachit Menon, Junfeng Yang, Xin Wang, Carl Vondrick
CVPR 2023
BibTeX
@inproceedings{mao2023doubly,
  title={Doubly Right Object Recognition: A Why Prompt for Visual Rationales},
  author={Chengzhi Mao and Revant Teotia and Amrutha Sundar and Sachit Menon and Junfeng Yang and Xin Wang and Carl Vondrick},
  booktitle={CVPR 2023},
  year={2023},
  url={https://arxiv.org/abs/2212.06202}
}
Affective Faces for Goal-Driven Dyadic Communication
Scott Geng*, Revant Teotia*, Purva Tendulkar, Sachit Menon, Carl Vondrick
arXiv 2023
@article{geng2023affective,
  title={Affective Faces for Goal-Driven Dyadic Communication},
  author={Scott Geng and Revant Teotia and Purva Tendulkar and Sachit Menon and Carl Vondrick},
  journal={arXiv 2023},
  year={2023},
  url={https://arxiv.org/abs/2301.10939}
}
Visual Classification via Description from Large Language Models
Sachit Menon, Carl Vondrick
ICLR 2023 (Oral)
@inproceedings{menon2023visual,
  title={Visual Classification via Description from Large Language Models},
  author={Sachit Menon and Carl Vondrick},
  booktitle={ICLR 2023 (Oral)},
  year={2023},
  url={https://arxiv.org/abs/2210.07183}
}
Understanding Zero-Shot Adversarial Robustness for Large-Scale Models
Chengzhi Mao, Scott Geng, Junfeng Yang, Xin Wang, Carl Vondrick
ICLR 2023
BibTeX
@inproceedings{mao2023understanding,
  title={Understanding Zero-Shot Adversarial Robustness for Large-Scale Models},
  author={Chengzhi Mao and Scott Geng and Junfeng Yang and Xin Wang and Carl Vondrick},
  booktitle={ICLR 2023},
  year={2023},
  url={https://arxiv.org/abs/2212.07016}
}
2022
Adversarially Robust Video Perception by Seeing Motion
Lingyu Zhang*, Chengzhi Mao*, Junfeng Yang, Carl Vondrick
arXiv 2022
@article{zhang2022adversarially,
  title={Adversarially Robust Video Perception by Seeing Motion},
  author={Lingyu Zhang and Chengzhi Mao and Junfeng Yang and Carl Vondrick},
  journal={arXiv 2022},
  year={2022},
  url={https://arxiv.org/abs/2212.07815}
}
Task Bias in Vision-Language Models
Sachit Menon*, Ishaan Preetam Chandratreya*, Carl Vondrick
arXiv 2022
BibTeX
@article{menon2022task,
  title={Task Bias in Vision-Language Models},
  author={Sachit Menon and Ishaan Preetam Chandratreya and Carl Vondrick},
  journal={arXiv 2022},
  year={2022},
  url={https://arxiv.org/pdf/2212.04412.pdf}
}
Private Multiparty Perception for Navigation
Hui Lu, Mia Chiquier, Carl Vondrick
NeurIPS 2022
@inproceedings{lu2022private,
  title={Private Multiparty Perception for Navigation},
  author={Hui Lu and Mia Chiquier and Carl Vondrick},
  booktitle={NeurIPS 2022},
  year={2022},
  url={https://arxiv.org/abs/2212.00912}
}
Representing Spatial Trajectories as Distributions
Dídac Surís, Carl Vondrick
NeurIPS 2022
@inproceedings{surís2022representing,
  title={Representing Spatial Trajectories as Distributions},
  author={Dídac Surís and Carl Vondrick},
  booktitle={NeurIPS 2022},
  year={2022},
  url={https://trajectories.cs.columbia.edu}
}
Forget-me-not! Contrastive Critics for Mitigating Posterior Collapse
Sachit Menon, David Blei, Carl Vondrick
UAI 2022
BibTeX
@inproceedings{menon2022forgetmenot,
  title={Forget-me-not! Contrastive Critics for Mitigating Posterior Collapse},
  author={Sachit Menon and David Blei and Carl Vondrick},
  booktitle={UAI 2022},
  year={2022},
  url={https://openreview.net/pdf?id=SrgIkwLjql9}
}
Revealing Occlusions with 4D Neural Fields
Basile Van Hoorick, Purva Tendulkar, Dídac Surís, Dennis Park, Simon Stent, Carl Vondrick
CVPR 2022 (Oral)
@inproceedings{hoorick2022revealing,
  title={Revealing Occlusions with 4D Neural Fields},
  author={Basile Van Hoorick and Purva Tendulkar and Dídac Surís and Dennis Park and Simon Stent and Carl Vondrick},
  booktitle={CVPR 2022 (Oral)},
  year={2022},
  url={https://arxiv.org/pdf/2204.10916.pdf}
}
Globetrotter: Connecting Languages by Connecting Images
Dídac Surís, Dave Epstein, Carl Vondrick
CVPR 2022 (Oral)
@inproceedings{surís2022globetrotter,
  title={Globetrotter: Connecting Languages by Connecting Images},
  author={Dídac Surís and Dave Epstein and Carl Vondrick},
  booktitle={CVPR 2022 (Oral)},
  year={2022},
  url={https://arxiv.org/pdf/2012.04631.pdf}
}
Causal Transportability for Visual Recognition
Chengzhi Mao*, Kevin Xia*, James Wang, Hao Wang, Junfeng Yang, Elias Bareinboim, Carl Vondrick
CVPR 2022
BibTeX
@inproceedings{mao2022causal,
  title={Causal Transportability for Visual Recognition},
  author={Chengzhi Mao and Kevin Xia and James Wang and Hao Wang and Junfeng Yang and Elias Bareinboim and Carl Vondrick},
  booktitle={CVPR 2022},
  year={2022},
  url={https://arxiv.org/abs/2204.12363}
}
It's Time for Artistic Correspondence in Music and Video
Dídac Surís, Carl Vondrick, Bryan Russell, Justin Salamon
CVPR 2022
@inproceedings{surís2022its,
  title={It's Time for Artistic Correspondence in Music and Video},
  author={Dídac Surís and Carl Vondrick and Bryan Russell and Justin Salamon},
  booktitle={CVPR 2022},
  year={2022},
  url={https://arxiv.org/pdf/2206.07148.pdf}
}
UnweaveNet: Unweaving Activity Stories
Will Price, Carl Vondrick, Dima Damen
CVPR 2022
BibTeX
@inproceedings{price2022unweavenet,
  title={UnweaveNet: Unweaving Activity Stories},
  author={Will Price and Carl Vondrick and Dima Damen},
  booktitle={CVPR 2022},
  year={2022},
  url={https://arxiv.org/abs/2112.10194}
}
There is a Time and Place for Reasoning Beyond the Image
Xingyu Fu, Ben Zhou, Ishaan Preetam Chandratreya, Carl Vondrick, Dan Roth
ACL 2022 (Oral)
@inproceedings{fu2022there,
  title={There is a Time and Place for Reasoning Beyond the Image},
  author={Xingyu Fu and Ben Zhou and Ishaan Preetam Chandratreya and Carl Vondrick and Dan Roth},
  booktitle={ACL 2022 (Oral)},
  year={2022},
  url={https://arxiv.org/abs/2203.00758}
}
Real-Time Neural Voice Camouflage
Mia Chiquier, Chengzhi Mao, Carl Vondrick
ICLR 2022 (Oral)
@inproceedings{chiquier2022realtime,
  title={Real-Time Neural Voice Camouflage},
  author={Mia Chiquier and Chengzhi Mao and Carl Vondrick},
  booktitle={ICLR 2022 (Oral)},
  year={2022},
  url={https://voicecamo.cs.columbia.edu}
}
Discrete Representations Strengthen Vision Transformer Robustness
Chengzhi Mao, Lu Jiang, Mostafa Dehghani, Carl Vondrick, Rahul Sukthankar, Irfan Essa
ICLR 2022
BibTeX
@inproceedings{mao2022discrete,
  title={Discrete Representations Strengthen Vision Transformer Robustness},
  author={Chengzhi Mao and Lu Jiang and Mostafa Dehghani and Carl Vondrick and Rahul Sukthankar and Irfan Essa},
  booktitle={ICLR 2022},
  year={2022},
  url={https://arxiv.org/abs/2111.10493}
}
2021
Full-Body Visual Self-Modeling of Robot Morphologies
Boyuan Chen, Robert Kwiatkowski, Carl Vondrick, Hod Lipson
Science Robotics 2022
@article{chen2021fullbody,
  title={Full-Body Visual Self-Modeling of Robot Morphologies},
  author={Boyuan Chen and Robert Kwiatkowski and Carl Vondrick and Hod Lipson},
  journal={Science Robotics 2022},
  year={2021},
  url={https://robot-morphology.cs.columbia.edu}
}
The Boombox: Visual Reconstruction from Acoustic Vibrations
Boyuan Chen, Mia Chiquier, Hod Lipson, Carl Vondrick
CoRL 2021
@inproceedings{chen2021the,
  title={The Boombox: Visual Reconstruction from Acoustic Vibrations},
  author={Boyuan Chen and Mia Chiquier and Hod Lipson and Carl Vondrick},
  booktitle={CoRL 2021},
  year={2021},
  url={https://arxiv.org/abs/2105.08052}
}
Adversarial Attacks are Reversible with Natural Supervision
Chengzhi Mao, Mia Chiquier, Hao Wang, Junfeng Yang, Carl Vondrick
ICCV 2021
@inproceedings{mao2021adversarial,
  title={Adversarial Attacks are Reversible with Natural Supervision},
  author={Chengzhi Mao and Mia Chiquier and Hao Wang and Junfeng Yang and Carl Vondrick},
  booktitle={ICCV 2021},
  year={2021},
  url={https://arxiv.org/abs/2103.14222}
}
Learning the Predictability of the Future
Dídac Surís*, Ruoshi Liu*, Carl Vondrick
CVPR 2021
@inproceedings{surís2021learning,
  title={Learning the Predictability of the Future},
  author={Dídac Surís and Ruoshi Liu and Carl Vondrick},
  booktitle={CVPR 2021},
  year={2021},
  url={https://arxiv.org/pdf/2101.01600.pdf}
}
Generative Interventions for Causal Learning
Chengzhi Mao, Amogh Gupta, Augustine Cha, Hao Wang, Junfeng Yang, Carl Vondrick
CVPR 2021
@inproceedings{mao2021generative,
  title={Generative Interventions for Causal Learning},
  author={Chengzhi Mao and Amogh Gupta and Augustine Cha and Hao Wang and Junfeng Yang and Carl Vondrick},
  booktitle={CVPR 2021},
  year={2021},
  url={https://arxiv.org/abs/2012.12265}
}
Learning Goals from Failure
Dave Epstein, Carl Vondrick
CVPR 2021
@inproceedings{epstein2021learning,
  title={Learning Goals from Failure},
  author={Dave Epstein and Carl Vondrick},
  booktitle={CVPR 2021},
  year={2021},
  url={https://arxiv.org/pdf/2006.15657.pdf}
}
Visual Behavior Modelling for Robotic Theory of Mind
Boyuan Chen, Carl Vondrick, Hod Lipson
Scientific Reports 2021
@article{chen2021visual,
  title={Visual Behavior Modelling for Robotic Theory of Mind},
  author={Boyuan Chen and Carl Vondrick and Hod Lipson},
  journal={Scientific Reports 2021},
  year={2021},
  url={https://www.nature.com/articles/s41598-020-77918-x}
}
2020
Listening to Sounds of Silence for Speech Denoising
Ruilin Xu, Rundi Wu, Yuko Ishiwaka, Carl Vondrick, Changxi Zheng
NeurIPS 2020
@inproceedings{xu2020listening,
  title={Listening to Sounds of Silence for Speech Denoising},
  author={Ruilin Xu and Rundi Wu and Yuko Ishiwaka and Carl Vondrick and Changxi Zheng},
  booktitle={NeurIPS 2020},
  year={2020},
  url={http://www.cs.columbia.edu/cg/listen_to_the_silence/paper.pdf}
}
Multitask Learning Strengthens Adversarial Robustness
Chengzhi Mao, Amogh Gupta, Vikram Nitin, Baishakhi Ray, Shuran Song, Junfeng Yang, Carl Vondrick
ECCV 2020 (Oral)
BibTeX
@inproceedings{mao2020multitask,
  title={Multitask Learning Strengthens Adversarial Robustness},
  author={Chengzhi Mao and Amogh Gupta and Vikram Nitin and Baishakhi Ray and Shuran Song and Junfeng Yang and Carl Vondrick},
  booktitle={ECCV 2020 (Oral)},
  year={2020},
  url={https://arxiv.org/pdf/2007.07236.pdf}
}
We Have So Much In Common: Modeling Semantic Relational Set Abstractions in Videos
Alex Andonian, Camilo Fosco, Mathew Monfort, Allen Lee, Carl Vondrick, Rogerio Feris
ECCV 2020
@inproceedings{andonian2020we,
  title={We Have So Much In Common: Modeling Semantic Relational Set Abstractions in Videos},
  author={Alex Andonian and Camilo Fosco and Mathew Monfort and Allen Lee and Carl Vondrick and Rogerio Feris},
  booktitle={ECCV 2020},
  year={2020},
  url={https://arxiv.org/abs/2008.05596}
}
Learning to Learn Words from Visual Scenes
Dídac Surís*, Dave Epstein*, Heng Ji, Shih-Fu Chang, Carl Vondrick
ECCV 2020
@inproceedings{surís2020learning,
  title={Learning to Learn Words from Visual Scenes},
  author={Dídac Surís and Dave Epstein and Heng Ji and Shih-Fu Chang and Carl Vondrick},
  booktitle={ECCV 2020},
  year={2020},
  url={https://arxiv.org/pdf/1911.11237.pdf}
}
Oops! Predicting Unintentional Action in Video
Dave Epstein, Boyuan Chen, Carl Vondrick
CVPR 2020
@inproceedings{epstein2020oops,
  title={Oops! Predicting Unintentional Action in Video},
  author={Dave Epstein and Boyuan Chen and Carl Vondrick},
  booktitle={CVPR 2020},
  year={2020},
  url={https://arxiv.org/pdf/1911.11206.pdf}
}
2019
Metric Learning for Adversarial Robustness
Chengzhi Mao, Ziyuan Zhong, Junfeng Yang, Carl Vondrick, Baishakhi Ray
NeurIPS 2019
@inproceedings{mao2019metric,
  title={Metric Learning for Adversarial Robustness},
  author={Chengzhi Mao and Ziyuan Zhong and Junfeng Yang and Carl Vondrick and Baishakhi Ray},
  booktitle={NeurIPS 2019},
  year={2019},
  url={https://arxiv.org/abs/1909.00900}
}
VideoBERT: A Joint Model for Video and Language Representation Learning
Chen Sun, Austin Myers, Carl Vondrick, Kevin Murphy, Cordelia Schmid
ICCV 2019
@inproceedings{sun2019videobert,
  title={VideoBERT: A Joint Model for Video and Language Representation Learning},
  author={Chen Sun and Austin Myers and Carl Vondrick and Kevin Murphy and Cordelia Schmid},
  booktitle={ICCV 2019},
  year={2019},
  url={https://arxiv.org/abs/1904.01766}
}
Multi-level Multimodal Common Semantic Space for Image-Phrase Grounding
Hassan Akbari, Svebor Karaman, Surabhi Bhargava, Brian Chen, Carl Vondrick, Shih-Fu Chang
CVPR 2019
@inproceedings{akbari2019multilevel,
  title={Multi-level Multimodal Common Semantic Space for Image-Phrase Grounding},
  author={Hassan Akbari and Svebor Karaman and Surabhi Bhargava and Brian Chen and Carl Vondrick and Shih-Fu Chang},
  booktitle={CVPR 2019},
  year={2019},
  url={https://arxiv.org/pdf/1811.11683.pdf}
}
Relational Action Forecasting
Chen Sun, Abhinav Shrivastava, Carl Vondrick, Rahul Sukthankar, Kevin Murphy, Cordelia Schmid
CVPR 2019
BibTeX
@inproceedings{sun2019relational,
  title={Relational Action Forecasting},
  author={Chen Sun and Abhinav Shrivastava and Carl Vondrick and Rahul Sukthankar and Kevin Murphy and Cordelia Schmid},
  booktitle={CVPR 2019},
  year={2019},
  url={https://arxiv.org/abs/1904.04231}
}
Moments in Time Dataset: one million videos for event understanding
Mathew Monfort et al.
PAMI 2019
@article{monfort2019moments,
  title={Moments in Time Dataset: one million videos for event understanding},
  author={Mathew Monfort and others},
  journal={PAMI 2019},
  year={2019},
  url={http://moments.csail.mit.edu/}
}
2018
Tracking Emerges by Colorizing Videos
Carl Vondrick, Abhinav Shrivastava, Alireza Fathi, Sergio Guadarrama, Kevin Murphy
ECCV 2018
@inproceedings{vondrick2018tracking,
  title={Tracking Emerges by Colorizing Videos},
  author={Carl Vondrick and Abhinav Shrivastava and Alireza Fathi and Sergio Guadarrama and Kevin Murphy},
  booktitle={ECCV 2018},
  year={2018},
  url={https://arxiv.org/pdf/1806.09594.pdf}
}
The Sound of Pixels
Hang Zhao, Chuang Gan, Andrew Rouditchenko, Carl Vondrick, Josh McDermott, Antonio Torralba
ECCV 2018
@inproceedings{zhao2018the,
  title={The Sound of Pixels},
  author={Hang Zhao and Chuang Gan and Andrew Rouditchenko and Carl Vondrick and Josh McDermott and Antonio Torralba},
  booktitle={ECCV 2018},
  year={2018},
  url={https://arxiv.org/abs/1804.03160}
}
Actor-centric Relation Network
Chen Sun, Abhinav Shrivastava, Carl Vondrick, Kevin Murphy, Rahul Sukthankar, Cordelia Schmid
ECCV 2018
BibTeX
@inproceedings{sun2018actorcentric,
  title={Actor-centric Relation Network},
  author={Chen Sun and Abhinav Shrivastava and Carl Vondrick and Kevin Murphy and Rahul Sukthankar and Cordelia Schmid},
  booktitle={ECCV 2018},
  year={2018},
  url={https://arxiv.org/pdf/1807.10982.pdf}
}
AVA: A Video Dataset of Spatio-temporally Localized Atomic Visual Actions
Chunhui Gu et al.
CVPR 2018 (Spotlight)
@inproceedings{gu2018ava,
  title={AVA: A Video Dataset of Spatio-temporally Localized Atomic Visual Actions},
  author={Chunhui Gu and others},
  booktitle={CVPR 2018 (Spotlight)},
  year={2018},
  url={https://arxiv.org/abs/1705.08421}
}
2017
Following Gaze in Video
Adria Recasens, Carl Vondrick, Aditya Khosla, Antonio Torralba
ICCV 2017
BibTeX
@inproceedings{recasens2017following,
  title={Following Gaze in Video},
  author={Adria Recasens and Carl Vondrick and Aditya Khosla and Antonio Torralba},
  booktitle={ICCV 2017},
  year={2017},
  url={https://www.cs.columbia.edu/~vondrick/videogaze.pdf}
}
Generating the Future with Adversarial Transformers
Carl Vondrick, Antonio Torralba
CVPR 2017
@inproceedings{vondrick2017generating,
  title={Generating the Future with Adversarial Transformers},
  author={Carl Vondrick and Antonio Torralba},
  booktitle={CVPR 2017},
  year={2017},
  url={https://www.cs.columbia.edu/~vondrick/transformer.pdf}
}
Cross-Modal Scene Networks
Yusuf Aytar*, Lluis Castrejon*, Carl Vondrick, Hamed Pirsiavash, Antonio Torralba
PAMI 2017
@article{aytar2017crossmodal,
  title={Cross-Modal Scene Networks},
  author={Yusuf Aytar and Lluis Castrejon and Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  journal={PAMI 2017},
  year={2017},
  url={https://www.cs.columbia.edu/~vondrick/cmplaces_pami.pdf}
}
See, Hear, and Read: Deep Aligned Representations
Yusuf Aytar, Carl Vondrick, Antonio Torralba
arXiv 2017
@article{aytar2017see,
  title={See, Hear, and Read: Deep Aligned Representations},
  author={Yusuf Aytar and Carl Vondrick and Antonio Torralba},
  journal={arXiv 2017},
  year={2017},
  url={https://www.cs.columbia.edu/~vondrick/see-hear-read/}
}
2016
Generating Videos with Scene Dynamics
Carl Vondrick, Hamed Pirsiavash, Antonio Torralba
NeurIPS 2016
@inproceedings{vondrick2016generating,
  title={Generating Videos with Scene Dynamics},
  author={Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  booktitle={NeurIPS 2016},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/tinyvideo/}
}
SoundNet: Learning Sound Representations from Unlabeled Video
Yusuf Aytar*, Carl Vondrick*, Antonio Torralba
NeurIPS 2016
@inproceedings{aytar2016soundnet,
  title={SoundNet: Learning Sound Representations from Unlabeled Video},
  author={Yusuf Aytar and Carl Vondrick and Antonio Torralba},
  booktitle={NeurIPS 2016},
  year={2016},
  url={http://projects.csail.mit.edu/soundnet/}
}
Anticipating Visual Representations from Unlabeled Video
Carl Vondrick, Hamed Pirsiavash, Antonio Torralba
CVPR 2016 (Spotlight)
@inproceedings{vondrick2016anticipating,
  title={Anticipating Visual Representations from Unlabeled Video},
  author={Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  booktitle={CVPR 2016 (Spotlight)},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/prediction}
}
Predicting Motivations of Actions by Leveraging Text
Carl Vondrick, Deniz Oktay, Hamed Pirsiavash, Antonio Torralba
CVPR 2016
@inproceedings{vondrick2016predicting,
  title={Predicting Motivations of Actions by Leveraging Text},
  author={Carl Vondrick and Deniz Oktay and Hamed Pirsiavash and Antonio Torralba},
  booktitle={CVPR 2016},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/intention.pdf}
}
Learning Aligned Cross-Modal Representations from Weakly Aligned Data
Lluis Castrejon*, Yusuf Aytar*, Carl Vondrick, Hamed Pirsiavash, Antonio Torralba
CVPR 2016
@inproceedings{castrejon2016learning,
  title={Learning Aligned Cross-Modal Representations from Weakly Aligned Data},
  author={Lluis Castrejon and Yusuf Aytar and Carl Vondrick and Hamed Pirsiavash and Antonio Torralba},
  booktitle={CVPR 2016},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/adaptation.pdf}
}
Visualizing Object Detection Features
Carl Vondrick, Aditya Khosla, Hamed Pirsiavash, Tomasz Malisiewicz, Antonio Torralba
IJCV 2016
@article{vondrick2016visualizing,
  title={Visualizing Object Detection Features},
  author={Carl Vondrick and Aditya Khosla and Hamed Pirsiavash and Tomasz Malisiewicz and Antonio Torralba},
  journal={IJCV 2016},
  year={2016},
  url={https://www.cs.columbia.edu/~vondrick/ihog}
}
2015
Do We Need More Training Data?
Xiangxin Zhu, Carl Vondrick, Charless C. Fowlkes, Deva Ramanan
IJCV 2015
@article{zhu2015do,
  title={Do We Need More Training Data?},
  author={Xiangxin Zhu and Carl Vondrick and Charless C. Fowlkes and Deva Ramanan},
  journal={IJCV 2015},
  year={2015},
  url={https://www.cs.columbia.edu/~vondrick/bigdata.pdf}
}
Learning Visual Biases from Human Imagination
Carl Vondrick, Hamed Pirsiavash, Aude Oliva, Antonio Torralba
NeurIPS 2015
@inproceedings{vondrick2015learning,
  title={Learning Visual Biases from Human Imagination},
  author={Carl Vondrick and Hamed Pirsiavash and Aude Oliva and Antonio Torralba},
  booktitle={NeurIPS 2015},
  year={2015},
  url={https://www.cs.columbia.edu/~vondrick/imagination/paper.pdf}
}
Where are they looking?
Adria Recasens*, Aditya Khosla*, Carl Vondrick, Antonio Torralba
NeurIPS 2015
@inproceedings{recasens2015where,
  title={Where are they looking?},
  author={Adria Recasens and Aditya Khosla and Carl Vondrick and Antonio Torralba},
  booktitle={NeurIPS 2015},
  year={2015},
  url={https://www.cs.columbia.edu/~vondrick/gaze.pdf}
}
2014
Assessing the Quality of Actions
Hamed Pirsiavash, Carl Vondrick, Antonio Torralba
ECCV 2014
@inproceedings{pirsiavash2014assessing,
  title={Assessing the Quality of Actions},
  author={Hamed Pirsiavash and Carl Vondrick and Antonio Torralba},
  booktitle={ECCV 2014},
  year={2014},
  url={https://www.cs.columbia.edu/~vondrick/quality.pdf}
}
2013
HOGgles: Visualizing Object Detection Features
Carl Vondrick, Aditya Khosla, Tomasz Malisiewicz, Antonio Torralba
ICCV 2013 (Oral)
@inproceedings{vondrick2013hoggles,
  title={HOGgles: Visualizing Object Detection Features},
  author={Carl Vondrick and Aditya Khosla and Tomasz Malisiewicz and Antonio Torralba},
  booktitle={ICCV 2013 (Oral)},
  year={2013},
  url={https://www.cs.columbia.edu/~vondrick/ihog}
}
2012
Do We Need More Training Data or Better Models for Object Detection?
Xiangxin Zhu, Carl Vondrick, Deva Ramanan, Charless C. Fowlkes
BMVC 2012
@inproceedings{zhu2012do,
  title={Do We Need More Training Data or Better Models for Object Detection?},
  author={Xiangxin Zhu and Carl Vondrick and Deva Ramanan and Charless C. Fowlkes},
  booktitle={BMVC 2012},
  year={2012},
  url={https://www.cs.columbia.edu/~vondrick/largetrain.pdf}
}
Efficiently Scaling Up Crowdsourced Video Annotation
Carl Vondrick, Donald Patterson, Deva Ramanan
IJCV 2012
@article{vondrick2012efficiently,
  title={Efficiently Scaling Up Crowdsourced Video Annotation},
  author={Carl Vondrick and Donald Patterson and Deva Ramanan},
  journal={IJCV 2012},
  year={2012},
  url={https://www.cs.columbia.edu/~vondrick/vatic/ijcv.pdf}
}
2011
Video Annotation and Tracking with Active Learning
Carl Vondrick, Deva Ramanan
NeurIPS 2011
@inproceedings{vondrick2011video,
  title={Video Annotation and Tracking with Active Learning},
  author={Carl Vondrick and Deva Ramanan},
  booktitle={NeurIPS 2011},
  year={2011},
  url={https://www.cs.columbia.edu/~vondrick/vatic/videoalearn.pdf}
}
A Large-scale Benchmark Dataset for Event Recognition
Sangmin Oh et al.
CVPR 2011
@inproceedings{oh2011a,
  title={A Large-scale Benchmark Dataset for Event Recognition},
  author={Sangmin Oh and others},
  booktitle={CVPR 2011},
  year={2011},
  url={https://www.cs.columbia.edu/~vondrick/vatic/virat.pdf}
}
2010
Efficiently Scaling Up Video Annotation with Crowdsourced Marketplaces
Carl Vondrick, Deva Ramanan, Donald Patterson
ECCV 2010
@inproceedings{vondrick2010efficiently,
  title={Efficiently Scaling Up Video Annotation with Crowdsourced Marketplaces},
  author={Carl Vondrick and Deva Ramanan and Donald Patterson},
  booktitle={ECCV 2010},
  year={2010},
  url={https://www.cs.columbia.edu/~vondrick/vatic/scalingup.pdf}
}